


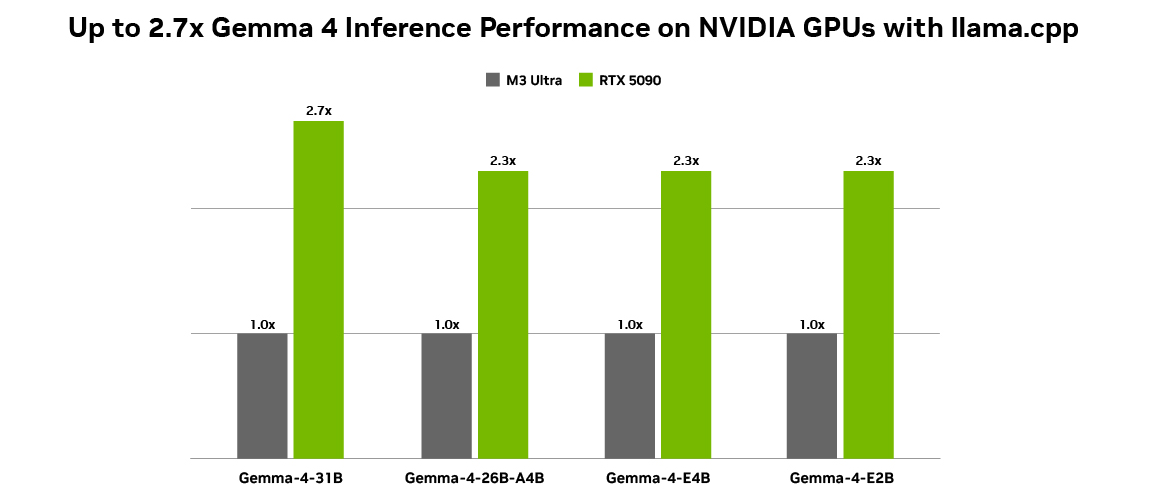
Open models are driving a new wave of on-device AI, extending innovation beyond the cloud to everyday devices. As these models advance, their value increasingly depends on access to local, real-time context that can turn meaningful insights into action.
Designed for this shift, Google’s latest additions to the Gemma 4 family introduce a class of small, fast and omni-capable models built for efficient local execution across a wide range of devices.
Google and NVIDIA have collaborated to optimize Gemma 4 for NVIDIA GPUs, enabling efficient performance across a range of systems — from data center deployments to NVIDIA RTX-powered PCs and workstations, the NVIDIA DGX Spark personal AI supercomputer and NVIDIA Jetson Orin Nano edge AI modules.
Gemma 4: Compact Models Optimized for NVIDIA GPUs
The latest additions to the Gemma 4 family of open models— spanning E2B, E4B, 26B and 31B variants — are designed for efficient deployment from edge devices to high-performance GPUs.

This new generation of compact models supports a range of tasks, including:
- Reasoning: Strong performance on complex problem-solving tasks.
- Coding: Code generation and debugging for developer workflows.
- Agents: Native support for structured tool use (function calling).
- Vision, Video and Audio Capabilities: Enables rich multimodal interactions for object recognition, automated speech recognition, and document or video intelligence.
- Interleaved Multimodal Input: Mix text and images in any order within a single prompt.
- Multilingual: Out-of-the-box support for 35+ languages, pretrained on 140+ languages.
The E2B and E4B models are built for ultraefficient, low-latency inference at the edge, running completely offline with near-zero latency across many devices including Jetson Nano modules.
The 26B and 31B modelsare designed for high-performance reasoning and developer-centric workflows, making them well suited for agentic AI. Optimized to deliver state-of-the-art, accessible reasoning, these models run efficiently on NVIDIA RTX GPUs and DGX Spark — powering development environments, coding assistants and agent-driven workflows.
As local agentic AI continues to gain momentum, applications like OpenClaw are enabling always-on AI assistants on RTX PCs, workstations and DGX Spark. The latest Gemma 4 models are compatible with OpenClaw, allowing users to build capable local agents that draw context from personal files, applications and workflows to automate tasks. Learn how to run OpenClaw for free on RTX GPUs and DGX Spark or using the DGX Spark OpenClaw playbook.
Check out the Google DeepMind announcement blog to learn more about the latest additions to Gemma 4 family.
Getting Started: Gemma 4 on RTX GPUs and DGX Spark
NVIDIA has collaborated with Ollama and llama.cpp to provide the best local deployment experience for each of the Gemma 4 models.
To use Gemma 4 locally, users can download Ollama to run Gemma 4 models or install llama.cpp and pair it with the Gemma 4 GGUF Hugging Face checkpoint. Additionally, Unsloth provides day-one support with optimized and quantized models for efficient local fine-tuning and deployment via Unsloth Studio. Start running and fine-tuning Gemma 4 in Unsloth Studio today.
Running open models like the Gemma 4 family on NVIDIA GPUs achieves optimal performance because NVIDIA Tensor Cores accelerate AI inference workloads to deliver higher throughput and lower latency for local execution. Plus, the CUDA software stack ensures broad compatibility across leading frameworks and tools, enabling new models to run efficiently from day one.
This combination allows open models like Gemma 4 to scale across a wide range of systems — from Jetson Orin Nano at the edge to RTX PCs, workstations and DGX Spark — without requiring extensive optimization.
Check out the NVIDIA technical blog for more details on how to get started with Gemma 4 on NVIDIA GPUs and learn more about NVIDIA’s work on open models.
#ICYMI: The Latest Updates for RTX AI PCs
 Catch up on RTX AI Garage blogs for a host of agentic AI announcements from NVIDIA GTC, such as new open models for local agents. These models include NVIDIA Nemotron 3 Nano 4B and Nemotron 3 Super 120B, and optimizations for Qwen 3.5 and Mistral Small 4.
NVIDIA recently introduced NVIDIA NemoClaw, an open source stack that optimizes OpenClaw experiences on NVIDIA devices by increasing security and supporting local models.
 Accomplish.ai announced Accomplish FREE, a no-cost version of its open source desktop AI agent with built-in models. It harnesses NVIDIA GPUs to run open weight models locally, while a hybrid router dynamically balances workloads between local RTX hardware and the cloud — enabling fast, private, zero-configuration execution without requiring an application programming interface key.
Plug in to NVIDIA AI PC on Facebook, Instagram, TikTok and X — and stay informed by subscribing to the RTX AI PC newsletter.







